Can Jev replace RAG or just improve retrieval?
We followed Jev, BM25 and embeddings from retrieval to generated answers on synthetic incidents. The completed study shows what improved, what failed and why RAG remains.
TL;DR: Jev improved evidence selection, but it did not replace RAG. In our completed answer study on 240 synthetic records, direct Jev plus a generator produced complete, correct answers on 20/20 answerable questions, versus 18/20 for the hybrid and 16/20 for both embeddings and BM25. All six arms refused the four no-answer questions. Diagnose where evidence disappears before changing your stack.
A search demo can look like an answer to the whole RAG problem. We wanted to follow the evidence further: from finding the right incident record to writing a correct explanation from it. We inspected Chat Seek, compared four retrieval methods, then ran the same answer generator on their saved outputs.
The result is a story about three separate decisions: which records enter the shortlist, which evidence reaches the writer, and what the writer says. Improving one decision does not remove the others.
What the demo actually replaces
Chat Seek v0.1.2 is a VS Code extension that helps developers find earlier Claude Code, Codex and OpenCode conversations from a plain-language description. Imagine remembering that you solved a PDF download problem with an AI coding assistant, but not which chat contains the fix. Chat Seek helps you return to that conversation instead of starting the investigation again.
That is retrieval: finding existing information that fits a question. Chat Seek returns conversation excerpts and lets you open the surrounding messages. Generation is a different step: writing a new answer from the information found. The original RAG paper combines retrieval with a language-generation model; the retrieved material gives the writer evidence to work from.
This makes the demo a useful starting point for our study. Finding the right conversation matters, but a team using an AI assistant also needs to know whether the evidence leads to a correct explanation. We therefore tested both stages: how hosted Jev selects evidence, and what a separate generator writes from the saved retrieval results. That connects search quality to the answer a reader actually receives.
Here is how the inspected Chat Seek implementation works. Its lexical scan looks for query terms in saved conversation records and retains up to 80 candidates. It then scores a smaller subset locally with Laya. Selected scores are blended with lexical scores; unselected candidates keep their lexical ranking signal.
This path uses local Laya, not hosted Jev. Laya's inspected ONNX export combines a ModernBERT encoder with a Laya decision head. Similar-looking interfaces do not make Laya and Jev the same model. Our hosted Jev measurements below are not measurements of Chat Seek or local Laya.
Our architectural conclusion is straightforward: replacing vector search changes the retrieval stage. If another model then writes an answer using the retrieved evidence, the overall application remains retrieval-augmented. Chat Seek itself finds old conversations rather than generating new answers, so it illustrates a retrieval workflow, not a replacement for a complete RAG system.
How we tested four retrieval methods
Imagine a QA team searching incident notes. Someone remembers a PDF download failure but not whether the cause was browser policy or a storage outage. Another person needs both a reproduction log and the release that fixed it.
We wrote synthetic records for that kind of work, then froze the documents, questions and relevance labels before the run. The same 24 questions were tested against nested collections of 24, 96 and 240 documents. Twenty questions had labeled evidence, including four requiring two records. Four deliberately had no answer.
The methods were:
BM25: a local keyword-ranking baseline, using lowercase word tokens.
Embeddings: local
all-MiniLM-L6-v2document and query vectors, ranked by exact cosine similarity. No hosted vector database was involved.BM25 plus Jev: the top eight keyword results, scored in one request with a separate Jev Noul relevance question for each candidate. Noul returns a yes probability.
Direct Jev: all documents supplied together, with a Choice selecting a document or
NONE, plus a separate question checking whether any evidence existed.
The remote retrieval model was pinned to jev-1.13.0, and every saved successful response returned that identifier. The retrieval phase made 144 real Jev requests and produced 288 method/query/scale rows. It did not generate answers. The follow-up answer study below used only the saved 240-document results, with no new retrieval calls.
We measured whether the first result was relevant, whether the top three contained the labeled evidence, and whether methods declined no-answer questions. Latency covered the online retrieval step, not initial document embedding.
Saved retrieval run: execution record
API failures: 0 across the 144 hosted Jev retrieval requests.
Reported input usage: 850,704 tokens for the retrieval phase; answer generation and semantic review are separate.
View the original retrieval-run dashboard screenshot
The linked view is our local viewer of saved synthetic-study outputs, not a provider dashboard. Timings combine different execution environments, not model-only speed.
This was a small diagnostic, not a production leaderboard. The extra documents were mostly templated distractors. Labels were authored, not independently adjudicated. There was one run per condition, and abstention thresholds were not calibrated. Those limits are part of the result, not fine print.
First, could each method find the evidence?
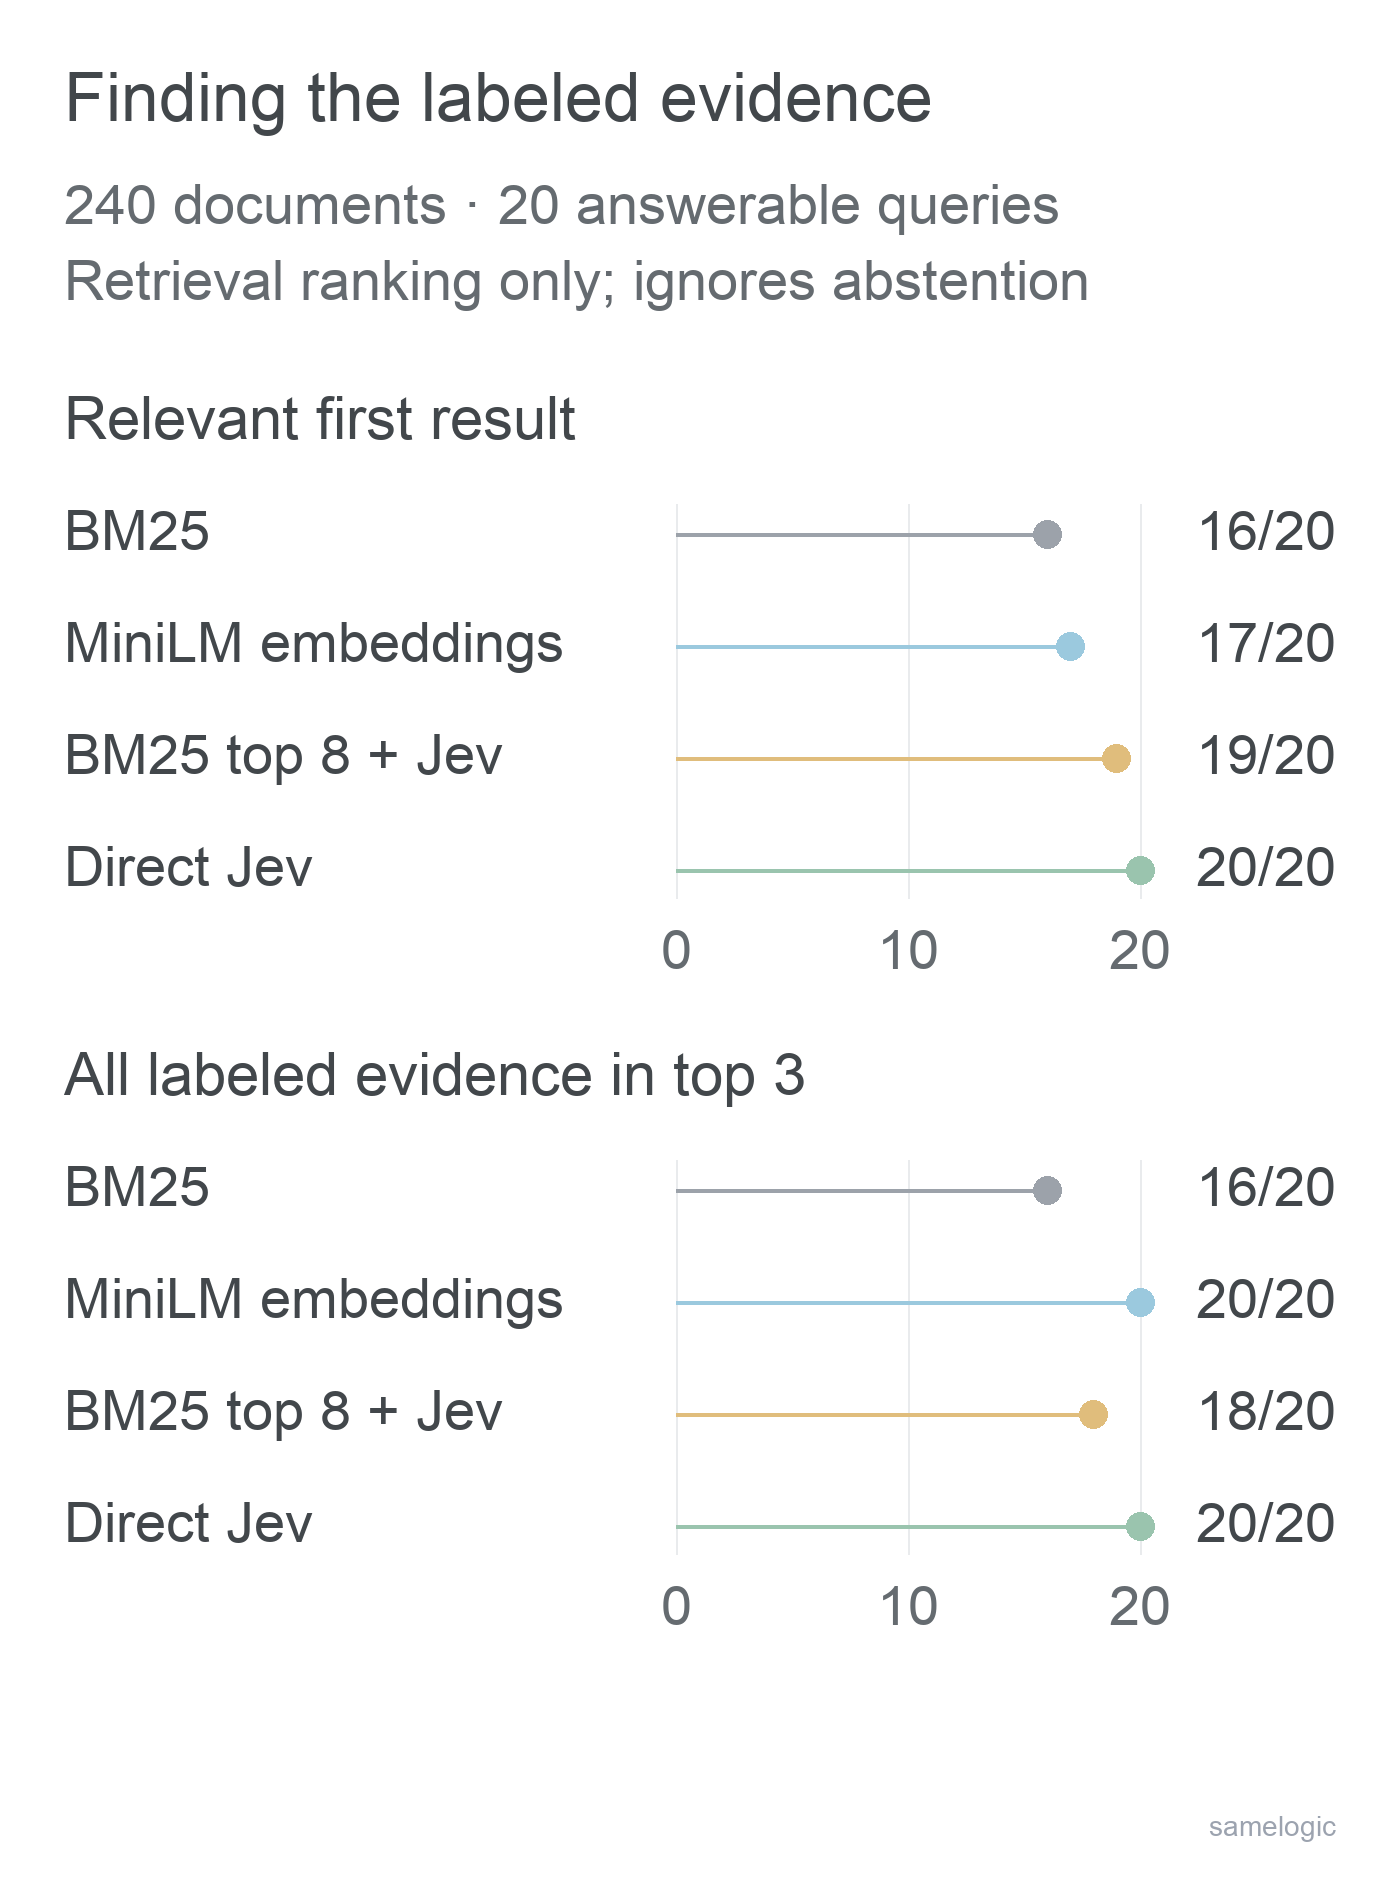
Retrieval only, at 240 documents and 20 answerable questions: BM25, embeddings, hybrid and direct Jev scored 80%, 85%, 95% and 100% on first-result relevance; evidence coverage in the top three was 80%, 100%, 90% and 100%. These ranking metrics ignore abstention. They are not the generated-answer scores reported below.
At 240 documents, direct Jev had the strongest first-result performance in this run.
Direct Jev reached 20/20 relevant first results at all three sizes. The embedding baseline remained at 17/20, but included every labeled evidence record within its top three. That makes “vectors failed” an inaccurate reading. For an application that passes several passages to a reader, evidence coverage may matter more than which passage comes first.
Q05 made that distinction concrete. It asked about a PDF incident with a successful HTTP status whose response the browser would not expose. Embeddings ranked a storage-outage record first and the labeled browser-policy record second. Both Jev methods put the browser-policy record first. Better ordering was useful, but the relevant evidence was not missing from the embedding shortlist.
Where retrieval still fails
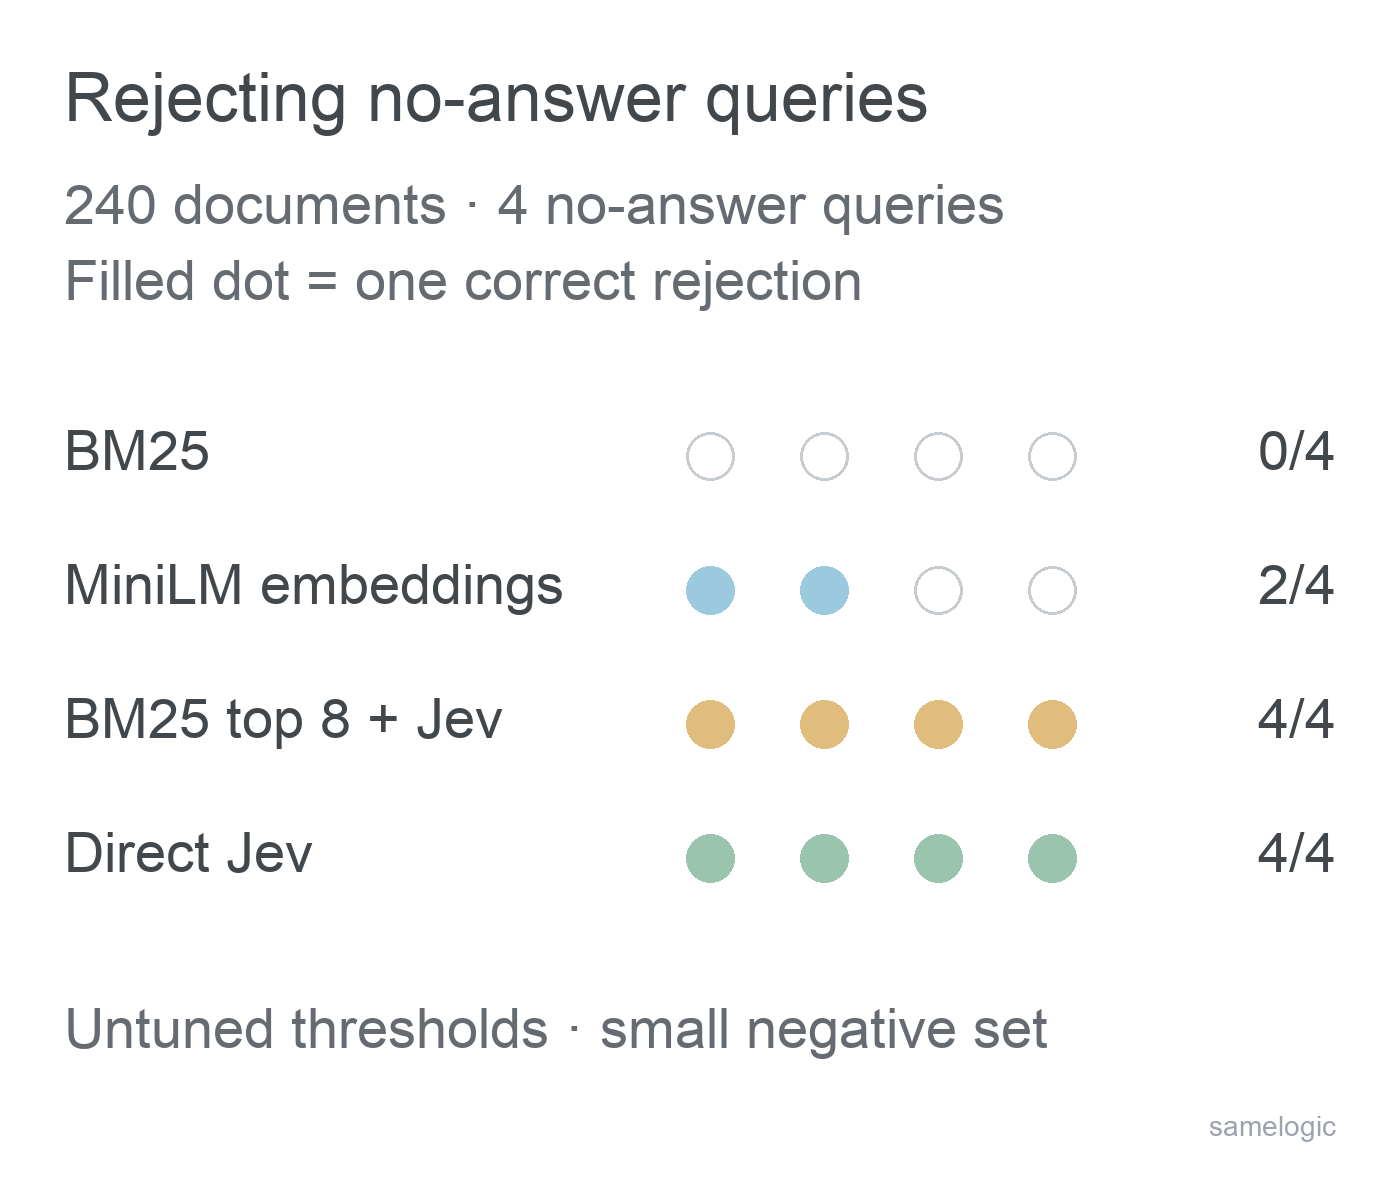
Only four no-answer questions at 240 documents: BM25 declined 0/4, embeddings 2/4, and both Jev pipelines 4/4. Thresholds were untuned. Four successes do not establish production reliability; this chart does not measure rejection of answerable questions.
Those abstention results deserve caution. Our embedding cutoff was an arbitrary cosine similarity of 0.5. The hybrid used a Noul cutoff of 0.5. Numerically identical thresholds do not mean equivalent decisions. TypeSafe also distinguishes relative Choice probabilities from separate yes/no judgments and warns against transferring thresholds between them.
The decision rules were BM25 top score ≤ 0; cosine < 0.5; hybrid maximum Noul < 0.5; and direct NONE or existence < 0.5. These different score spaces are not comparably calibrated.
Correctly declining a no-answer question is not the same as preserving evidence for an answerable one. The clearest retrieval failure happened before Jev could inspect the relevant record.
Q07: where the evidence disappeared
At 240 documents, Q07 asked why keyboard navigation falls out of a contacts scroller when rows disappear.
BM25 — rank 45: The relevant record, D006, fell below the keyword shortlist.
Top-eight cutoff: Only eight candidates reached Jev. D006 was not among them.
Jev — abstained: The supplied candidates scored poorly. Rejecting those weak matches still left this answerable question unanswered.
Embeddings and direct Jev — rank 1: Both ranked D006 first and accepted it.
D006 — Virtual list keyboard focus lost (synthetic corpus record)
Using Tab in the virtualized contact list jumps to the document body after scrolling. The focused row unmounts. Keep an active item mounted and restore focus by stable record ID.
View the original Q07 rankings and candidate-shortlist screenshot
This saved case illustrates the failure path; it is not a representative sample.
The practical lesson is to inspect candidate coverage before changing the reranker. A reranker cannot recover a record excluded from its input. Combining candidate sources or widening the shortlist is worth testing, but we did not run those variants here.
That left a harder question. Would a writer recover the right explanation from several passages, or carry a retrieval mistake into its answer? We tested that next, including the multi-record questions that require more than one good first result.
Then we asked the generator to answer
For the follow-up, each operational arm supplied its first three ranked records to the same GPT6 generator, unless the saved retrieval decision was to abstain. An abstention supplied no context, but the generator still ran. We kept full records intact under the same maximum evidence allowance. This was not an equal-length or hard total-token-matched test.
Two controls made the comparison easier to interpret. The no-context control always received nothing. The oracle control received exactly the labeled relevant records, not a production retrieval result. Each of the six arms faced the same 20 answerable and four no-answer questions from the 240-record corpus.
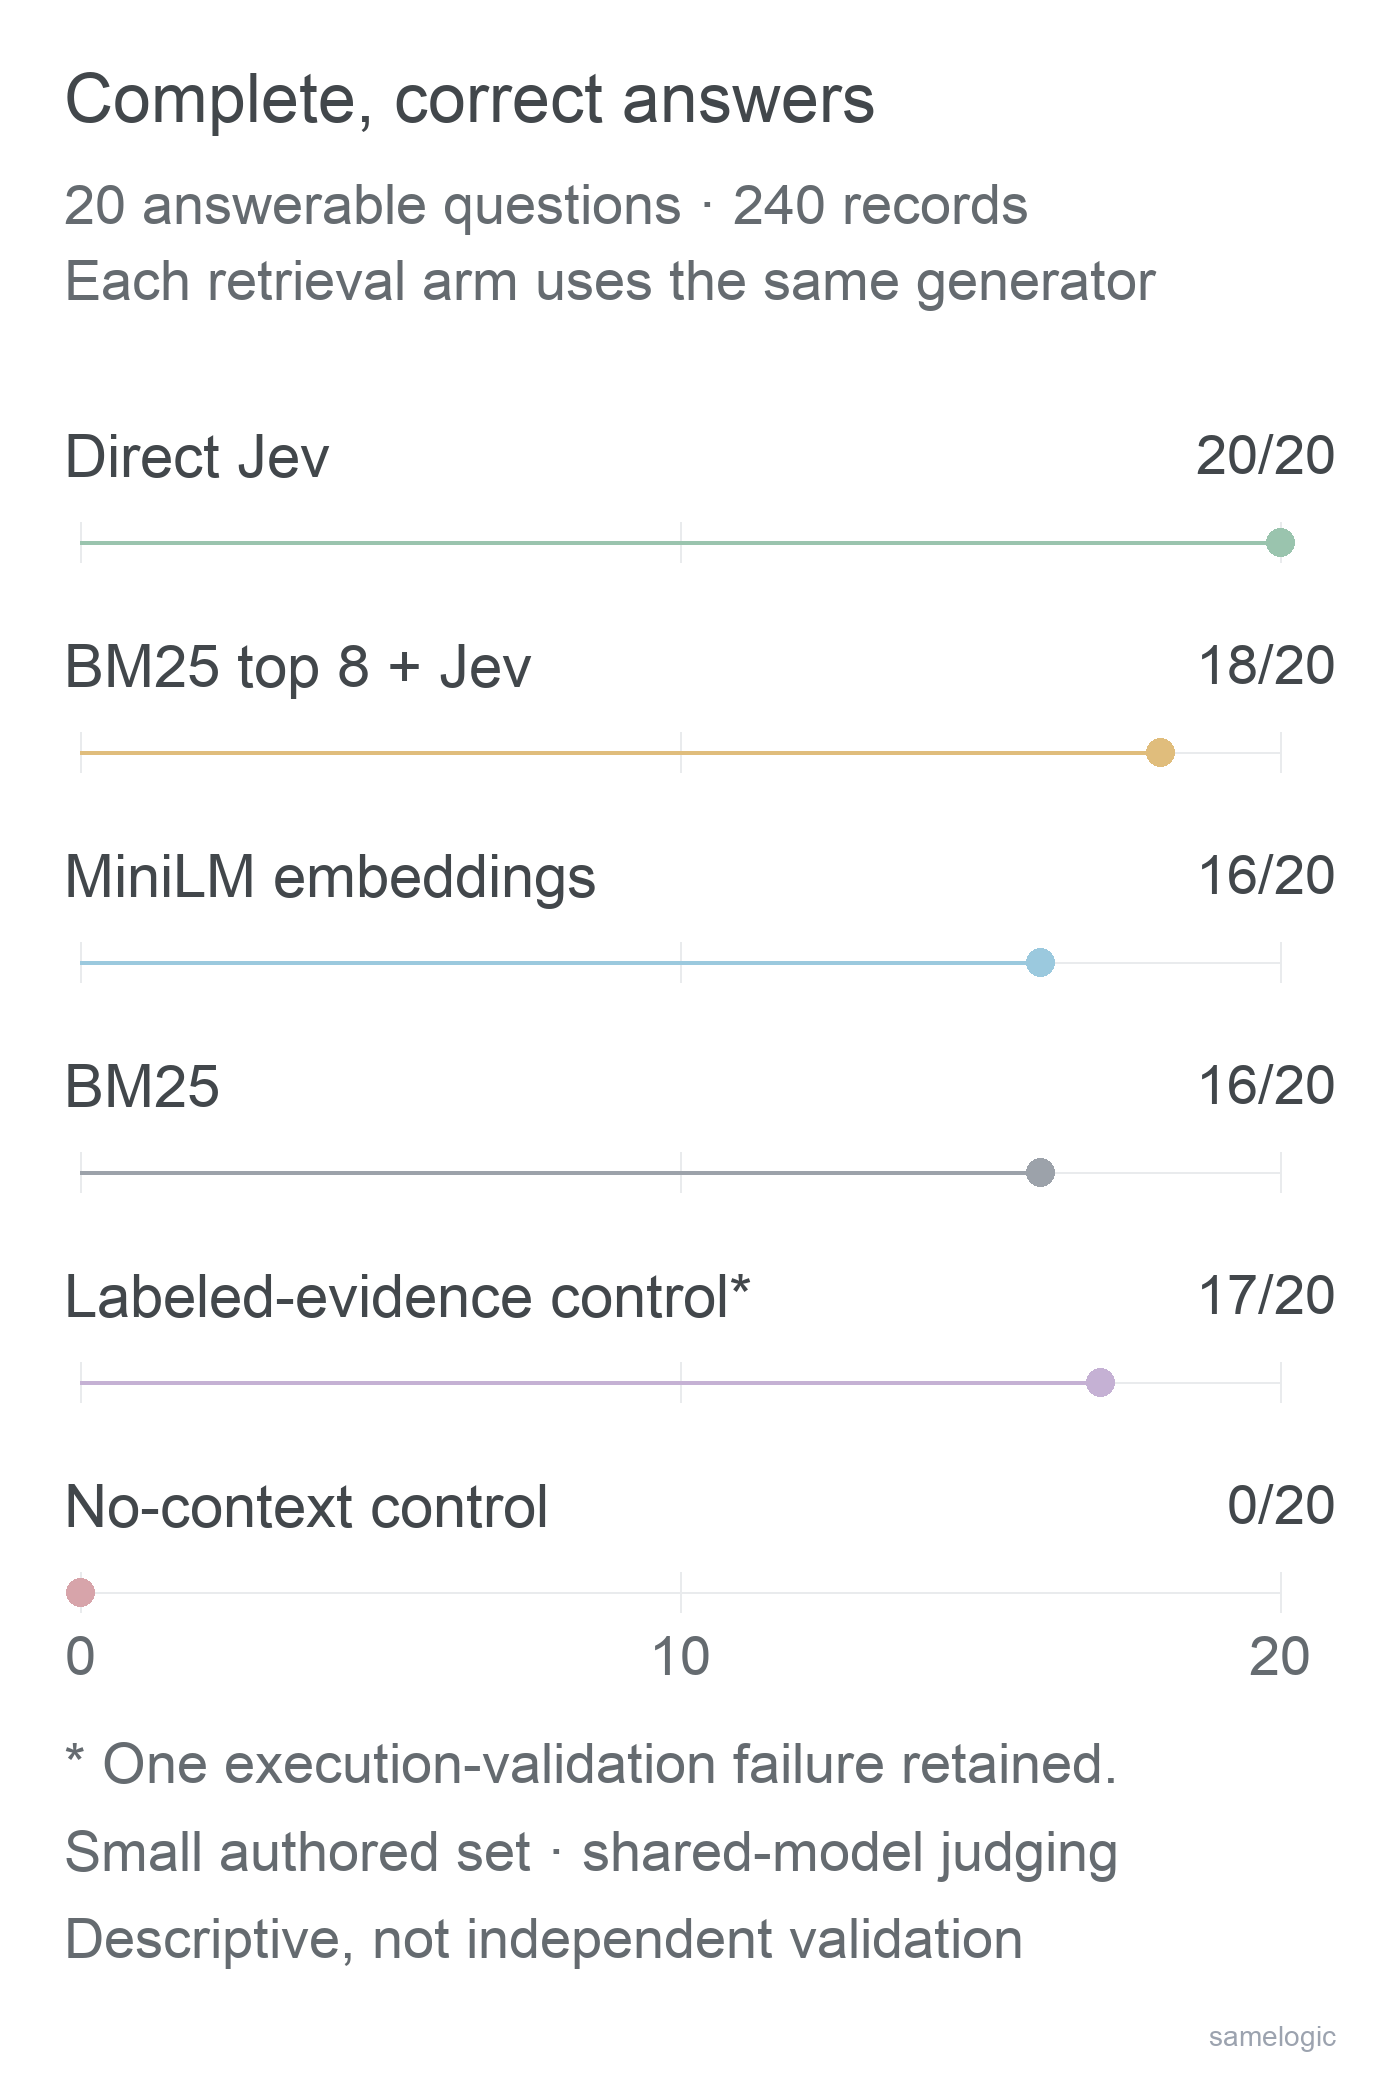
Complete, correct answers among 20 answerable questions per arm. Direct Jev + generator: 20/20; hybrid: 18/20; embeddings: 16/20; BM25: 16/20; labeled-evidence control: 17/20; no-context control: 0/20. The oracle denominator retains one execution-validation failure. Small authored synthetic set; shared-model judging limits the comparison.
We counted an answer as a complete success only when it covered all required content and all its factual claims were supported by the corpus. Supplied-evidence grounding and citation support were scored separately. A valid document ID alone did not establish that its passage supported the claim.
Direct Jev had the highest observed complete-answer count. The content-unit totals tell a similar story: direct 43/43, hybrid 40/43, embeddings 38/43, BM25 37/43, oracle 40/43 and no context 0/43. Those totals were the same for correct units and supplied-evidence-grounded units. The 43 rubric units are related pieces of content, not 43 independent observations.
The two incident examples explain more than a leaderboard alone. On Q05, the embedding arm produced a complete, correct answer even though the right record ranked second. On Q07, the hybrid still refused because its candidate stage had excluded the keyboard-focus record. Direct Jev and embeddings answered that question completely. A writer could use a lower-ranked passage; it could not restore evidence that never reached it.
All six arms correctly refused all four no-answer questions. That is a different result from the retrieval abstention chart above: a generator can decline an unsupported question even when retrieval returns weak candidates. Four cases do not establish reliable rejection in production. The no-context control also refused every answerable question, so its 0/20 answer completeness matters just as much as its 4/4 no-answer refusal.
The oracle control needs its own caution. It scored 17/20 complete successes, with one original Q05 execution-validation failure retained as a failure and two other answers failing the complete-success check. It was not retried or silently removed. This result does not show that perfect retrieval is worse: the control tests the writer and execution path too.
What the completed review can and cannot tell us
The primary generation run attempted 144 cells. Of those, 143 passed mechanical validation and all 143 received primary semantic review. Supplemental review covered all 62 selected answers; all 59 queued cases received two-pass adjudication, totaling 118 valid adjudication passes with no call failures. A queue entry was a review decision, not a count of wrong answers.
Two remaining truth-pass deferrals concerned whether a refusal was justified without knowing its supplied context. We closed those flags after unblinding by reconciling them with already-completed grounding passes showing empty context. No numeric performance score changed, and the original judgments remain preserved. This was a documented cross-pass closure, not a new blinded or human judgment.
The judging is not independent validation. Primary review was Claude-only for 110 answers, GPT6-only for 32, and mixed for one. GPT6 both generated the answers and performed supplemental review and adjudication. Claude grounding instructions included source-specific examples; later GPT6 guidance was procedural. These configuration differences and shared-model bias limit clean comparisons between arms.
This is a completed descriptive study, not a general winner claim. We reused a small authored synthetic set rather than a held-out production benchmark. Model aliases are mutable. No statistical significance or real-world superiority is established. Where an answer contained no factual claims or citations, the corresponding precision and citation rates are not applicable, not perfect.
Download the completed semantic-study results for final per-arm and per-question scores, completion counts and the two closure records. The separate retrieval archive remains linked in the evidence appendix.
What changes as the corpus grows
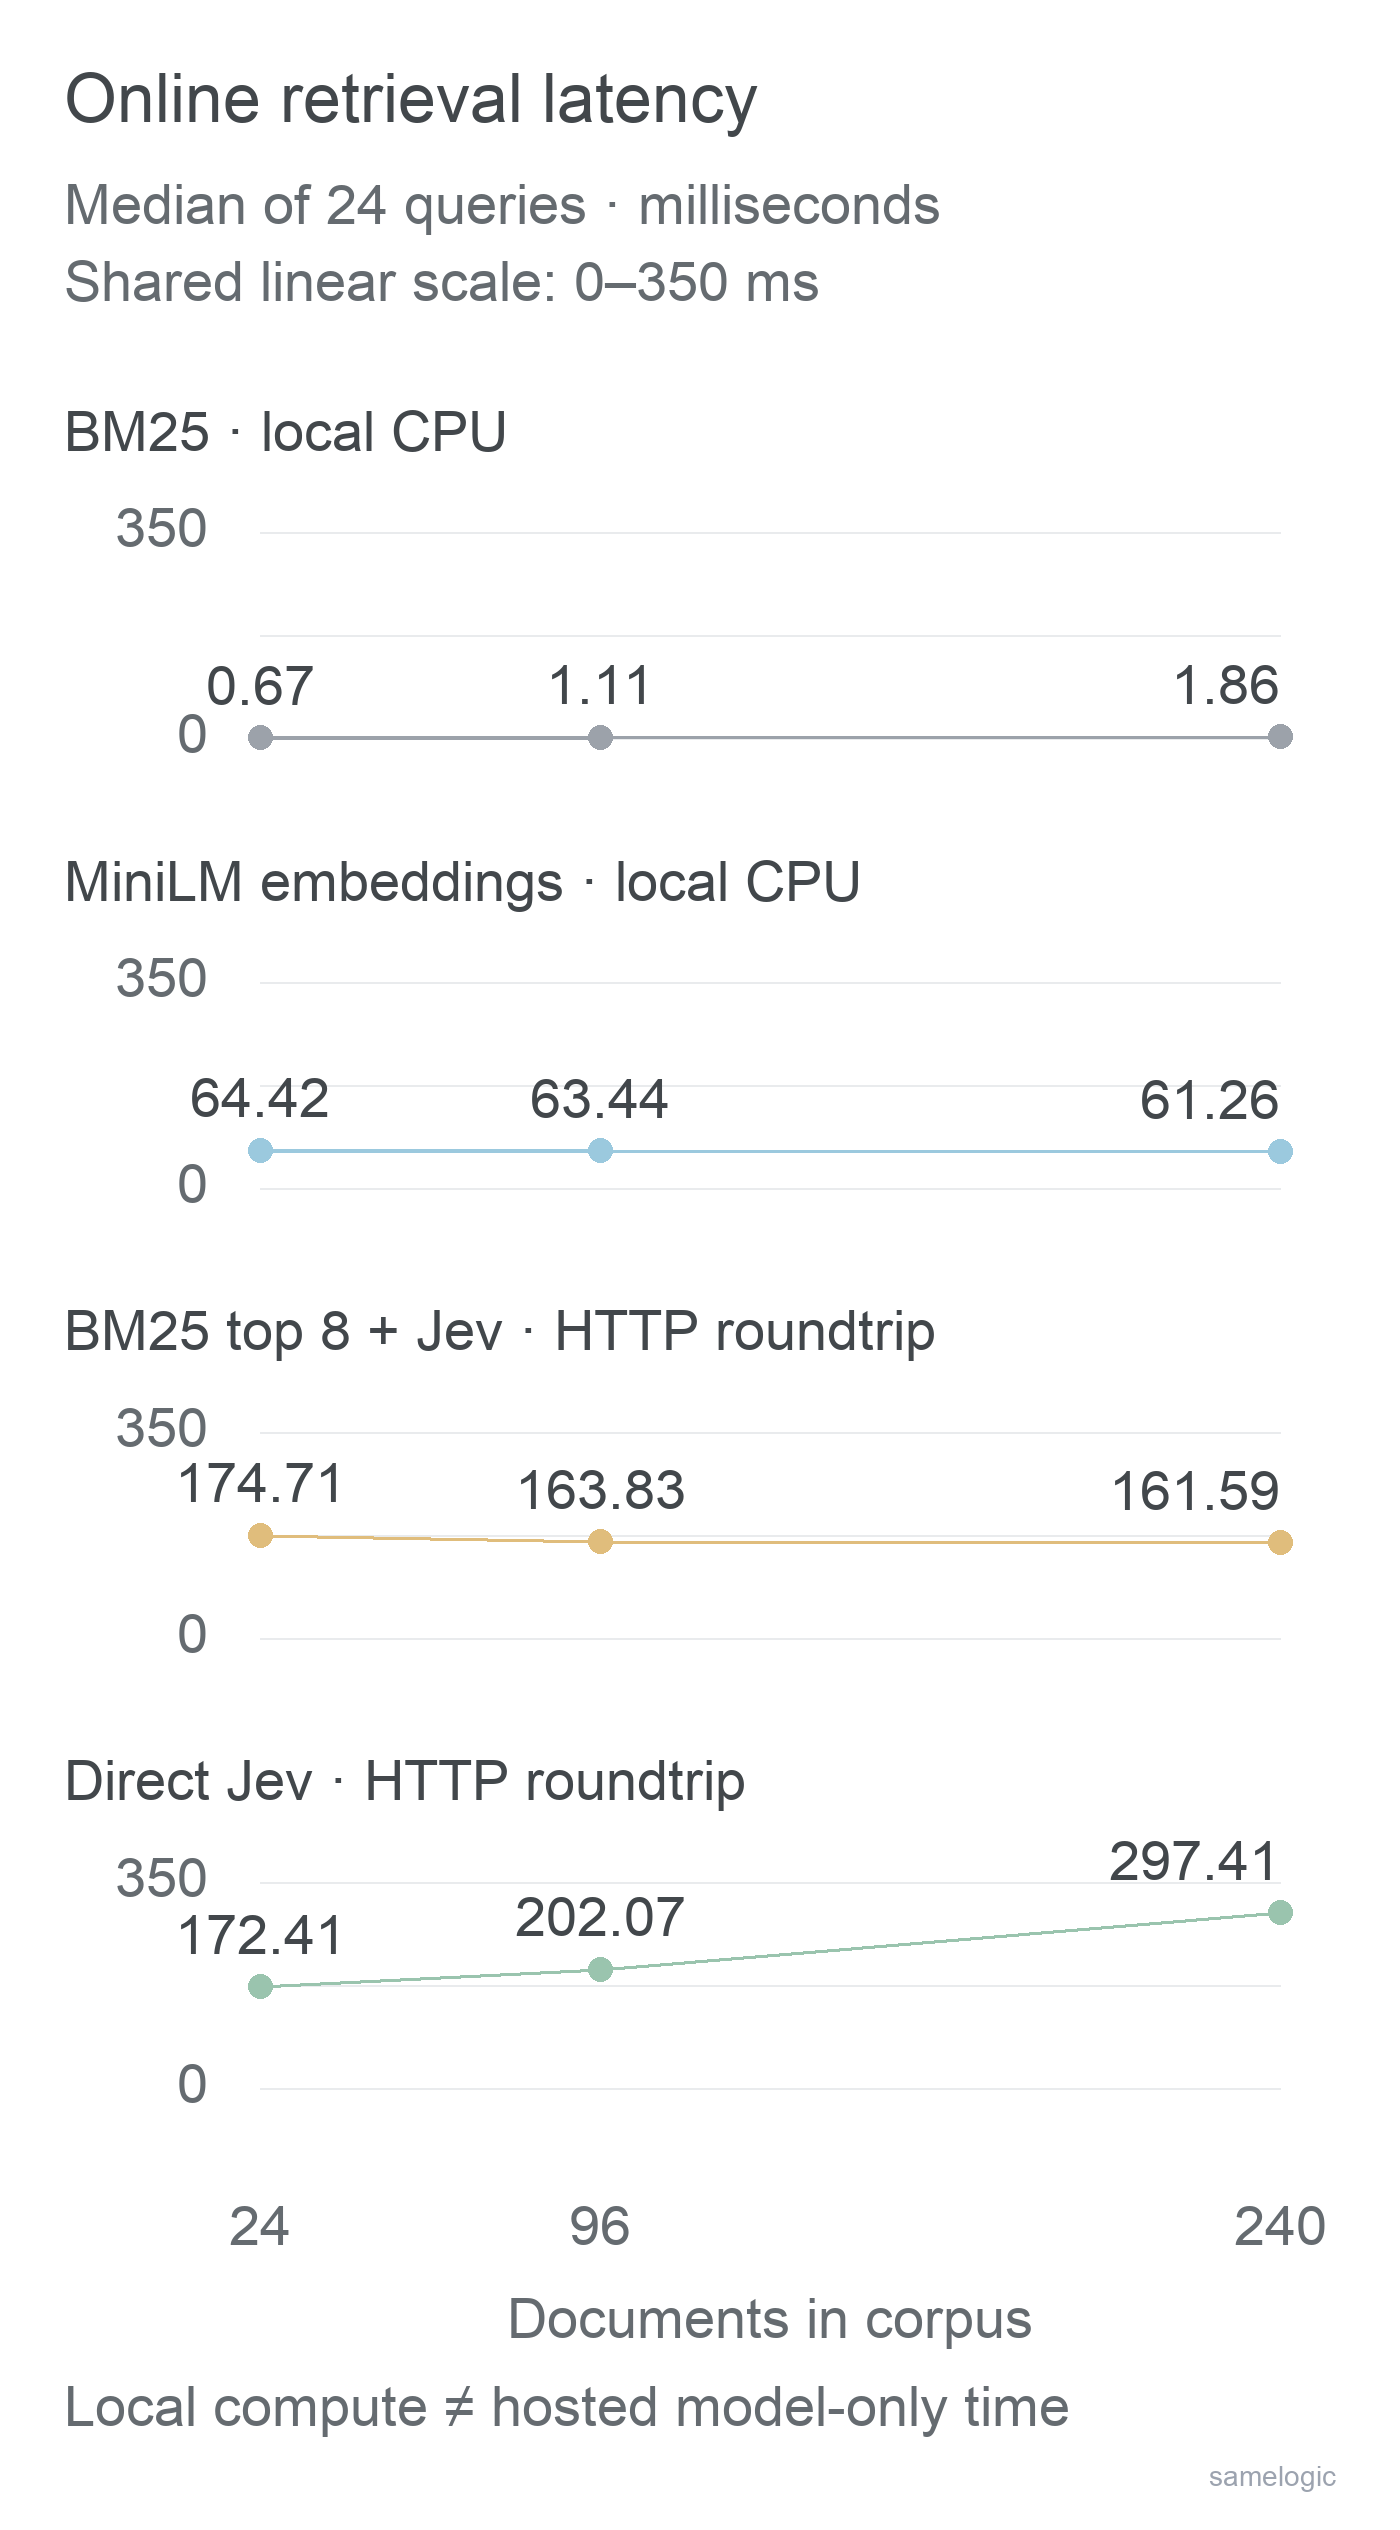
Median online retrieval latency across 24 queries per corpus size. Local CPU timings and hosted HTTP roundtrips are different execution conditions, not model-only speed comparisons. Query encoding is included; offline document encoding is excluded. One run per condition, without repeated timing trials or confidence intervals.
Direct selection's median HTTP roundtrip rose from 172.41 ms at 24 documents to 202.07 ms at 96 and 297.41 ms at 240.
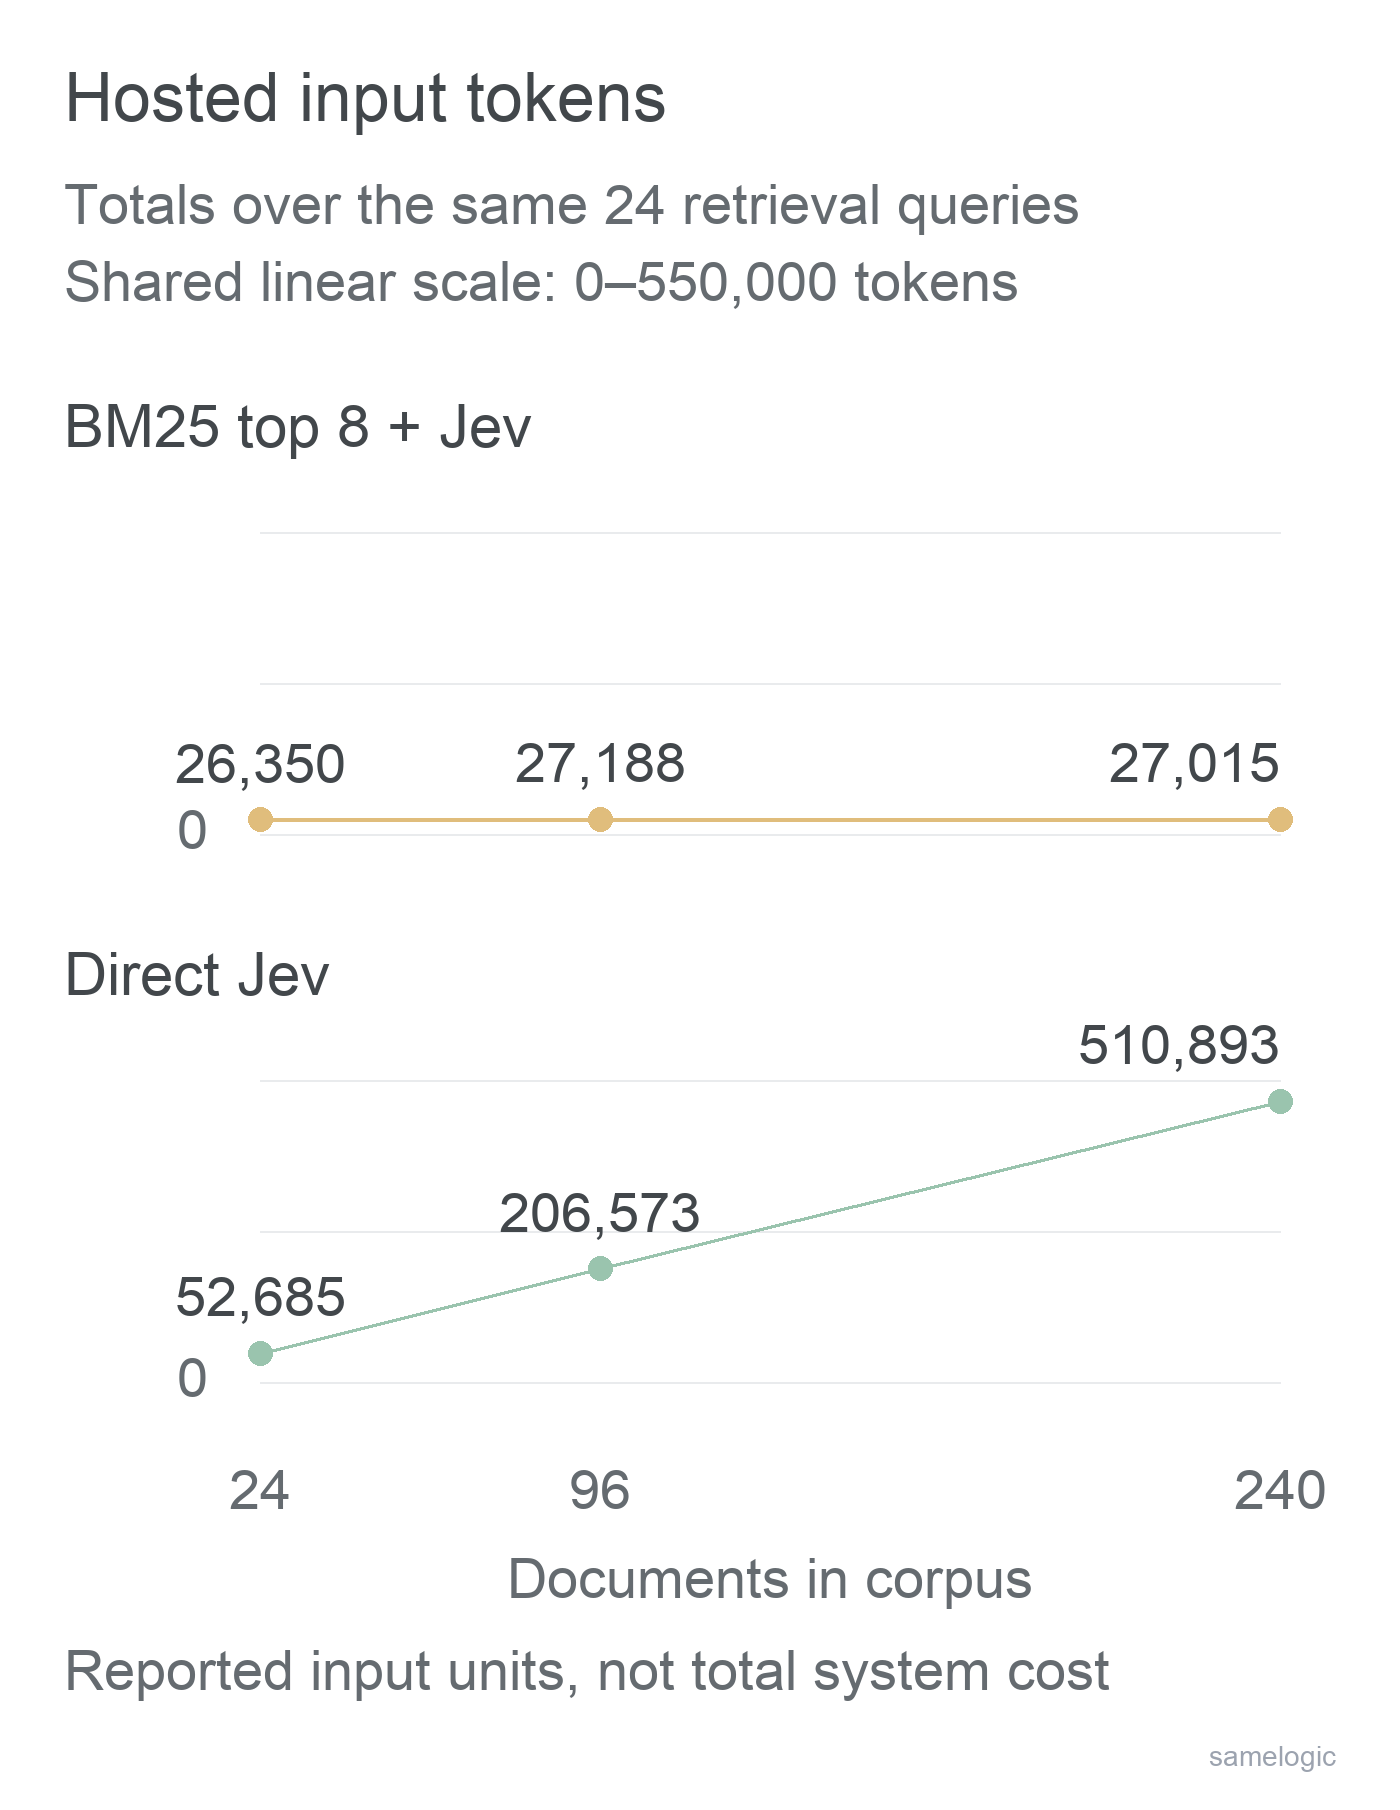
Reported hosted Jev input tokens, totaled over all 24 retrieval queries at each corpus size, not total system cost. Local methods use no hosted Jev tokens but still require compute and indexing. Mostly templated distractor growth in one synthetic study is not a production scaling law.
Direct Jev's reported input usage across the 24 questions rose from 52,685 to 206,573 to 510,893 tokens.
The eight-candidate hybrid used 26,350, 27,188 and 27,015 input tokens respectively. Keeping the shortlist small bounded what reached the hosted model, but candidate coverage suffered at the larger sizes. The keyboard-focus record was excluded, as was one required record in a separate two-evidence question.
Across the remote retrieval calls, reported input usage totaled 850,704 tokens. At the documented September 21, 2026 price of $0.042 per million input tokens, that implies about $0.0357 in input charges, with free output.This is a calculated retrieval-only estimate, not an invoice. It excludes local compute, engineering, answer generation and semantic review; actual subscription cost for the follow-up is unknown.
This is a trade-off, not a universal scaling law. We expanded mostly templated distractors around the same questions. We did not test millions of documents, long manuals, live updates, concurrent traffic or repeated timing trials.
There are also hard request boundaries. The documentation inspected on September 21 specifies 64k tokens for the total request and 32k for state plus the longest question. Choice supports up to 255 options; our largest direct request used 240 document options plus NONE.
An all-corpus prompt is therefore a bounded technique, not an unlimited index substitute. TypeSafe's own Jev limitations page recommends retrieving and filtering in code before sending irrelevant material to the model.Larger collections force another design decision: which evidence should the model see?
What this means for a retrieval stack
The completed answer review strengthens the case for evaluating Jev, not for declaring retrieval-augmented generation obsolete. Every operational answer arm still combined retrieval with a separate generator.
Consider direct Jev for a small, bounded collection when choosing among known records is the job. This experiment supports evaluating that pattern. It does not establish a safe universal corpus size or production reliability.
Consider Jev after retrieval when candidate coverage is already good. If the right record arrives but ranks below a plausible near-match, relevance scoring may help. If it never arrives, improve the first stage before celebrating reranker accuracy.
Keep retrieval and answer evaluation separate, then connect their failure cases. In this run, a second-ranked passage was enough for the embedding arm to answer Q05 correctly; an excluded record left the hybrid unable to answer Q07. TypeSafe's passage-classification cookbook also combines embedding retrieval, relevance filtering and a separate generator.These components can coexist.
Before adopting either pattern, build a held-out set from approved data, include no-answer and multi-record questions, and compare against the retrieval system you actually operate. Tune abstention separately from ranking. Keep permissions and exact date or numeric rules in application code. Our hosted experiment used synthetic records; it does not validate sending private conversations to that endpoint.
Our takeaway: direct Jev had the highest observed answer completeness in this bounded run, embeddings retained useful evidence despite imperfect first-place rankings, and the hybrid exposed the cost of a narrow keyword shortlist. Follow an unanswered question back through the evidence path. Change the stage that lost what the writer needed.
Evidence and study detail
The original retrieval downloads cover the frozen ranking experiment: results and limitations, method/query rows, queries, corpus, independent validation and editorial review. These links provide public downloads of the original retrieval evidence. The two screenshots are saved-output views, not new model executions.
Retrieval detail at 240 documents. The first two metric columns measure ranking on answerable questions, ignoring abstention. The third tests retrieval abstention on the four no-answer questions. None of these columns is generated-answer accuracy.
Method | Relevant first result | All labeled evidence in top three | Correctly declined no-answer questions | Median online latency |
|---|---|---|---|---|
BM25 | 16/20 | 16/20 | 0/4 | 1.86 ms |
Embeddings | 17/20 | 20/20 | 2/4 | 61.26 ms |
BM25 plus Jev | 19/20 | 18/20 | 4/4 | 161.59 ms |
Direct Jev | 20/20 | 20/20 | 4/4 | 297.41 ms |
Latency detail at 24, 96 and 240 documents, respectively: BM25 0.67, 1.11, 1.86 ms; local MiniLM embeddings 64.42, 63.44, 61.26 ms; BM25 top 8 + Jev 174.71, 163.83, 161.59 ms; direct Jev 172.41, 202.07, 297.41 ms.
Sources Chat Seek search implementation Chat Seek extension implementation Laya model card Original RAG paper Jev models and pricing Jev API reference Jev limitations Confidence guidance RAG passage classification
Related workflows
Move from editorial context into the selector, Playwright, and bug-reproduction pages that turn exact UI evidence into action.
 Install the Chrome Extension